Engineering groups working with custom speech synthesis frequently face challenges when configuring their hosting environments. According to Amazon Web Services, "Teams deploying custom text-to-speech models on Amazon SageMaker AI often guess at autoscaling thresholds" when managing their workloads. These unmeasured targets can trigger significant operational issues in production systems. In practice, "a wrong guess either wastes GPU spend or breaches a latency SLO."
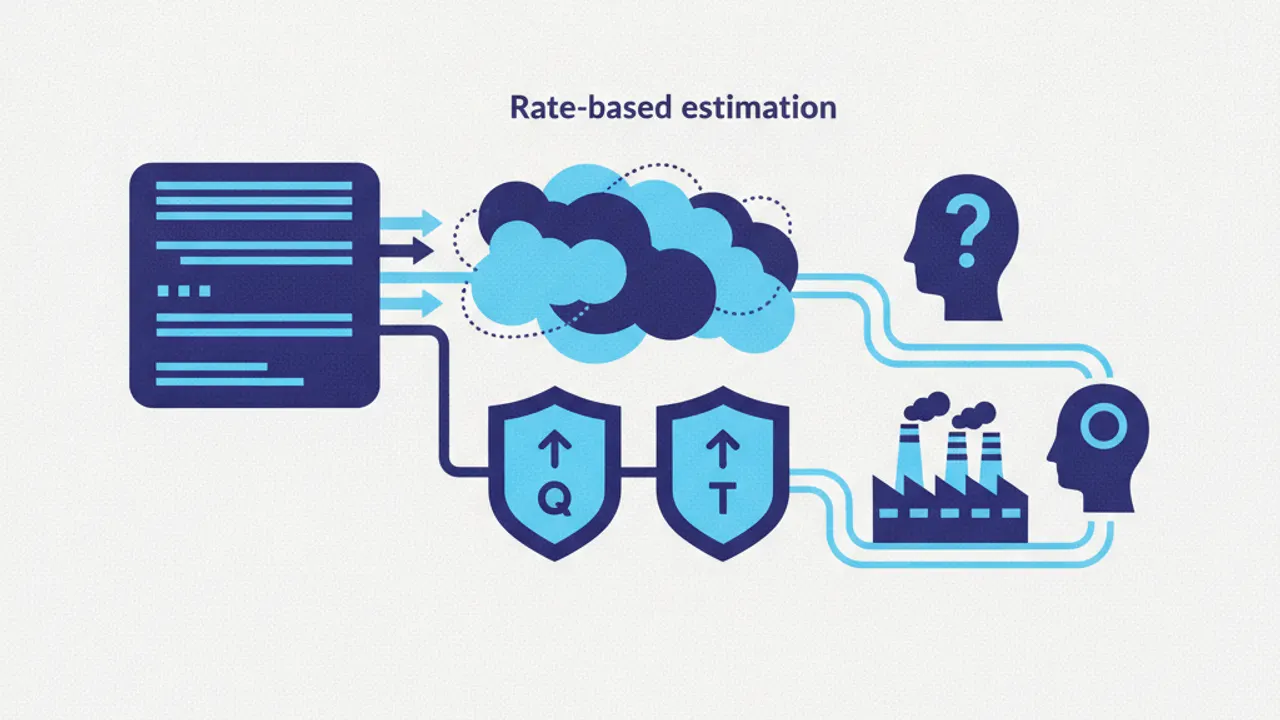
To address this inefficiency, an alternative deployment method relies on direct empirical evaluation. Under this setup, a technical walkthrough "deploys Kokoro-82M as a custom container" to evaluate actual serving capacity. The process replaces arbitrary rules with concrete observations gathered directly from active instances. Specifically, the framework "derives a measured autoscaling policy from two live-endpoint measurements, Q_max and T_total, instead of guesswork."