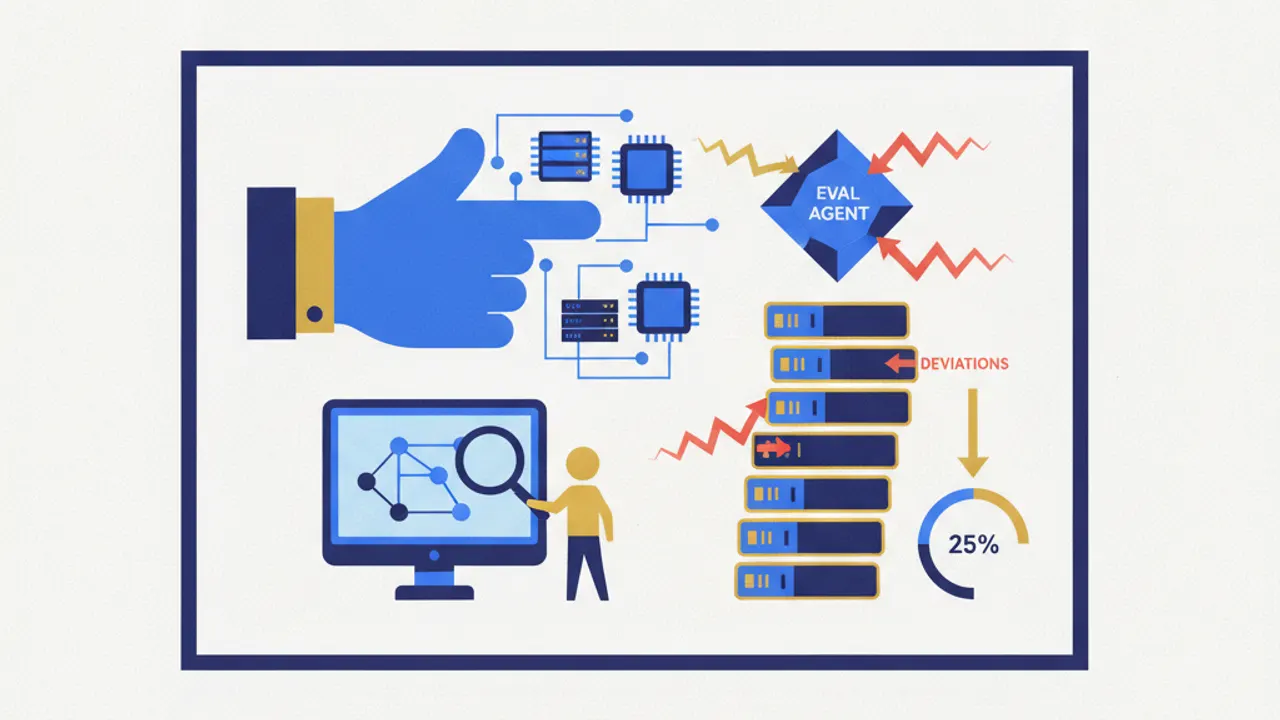
Terminal X has implemented an automated evaluation framework to assess generated material against structured benchmarks. According to project details, "Terminal X’s Eval Agent grades outputs against a 54-criterion rubric" during the review process. This specialized setup relies on "GPT-6.1 Sol" to inspect system responses against detailed criteria.
A key operational function of the agent is identifying discrepancies relative to investment parameters. Working with the new model configuration, the agent succeeds in "catching 25% more deviances from a fund’s mandate with GPT-6.1 Sol." The 54-criterion rubric provides the benchmark used to flag when outputs fail to align with a fund's formal operational directives.