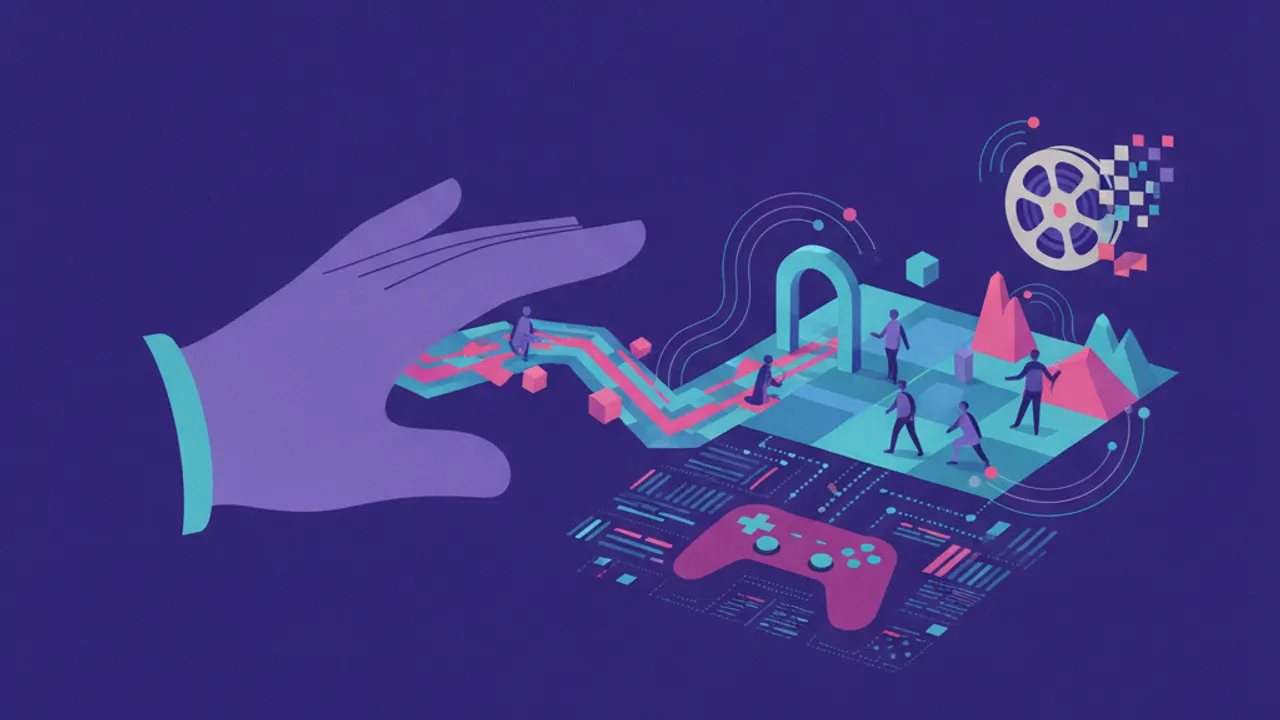
On October 27, 2026, Google DeepMind officially unveiled Genie 4, the next generation of its generative interactive world models. The system bridges the gap between multimodal neural networks and real-time virtual environments by converting simple text and image prompts into photorealistic, walkable 3D scenes. Users can immediately navigate through the generated worlds, as the simulation responds without perceivable lag to standard directional controls. With this release, Google DeepMind aims to dissolve the traditional boundary separating static media generation from fully interactive simulation.
Under the hood, the system is powered by the multimodal foundations of the Gemini family, utilizing Gemini 4 Argon in the background to handle complex reasoning. This underlying architecture ensures that the generated spaces do not merely present static imagery, but also react physically to keyboard and camera inputs. Rather than relying on pre-rendered assets or predefined physics engines, the neural framework computes spatial interactions dynamically during runtime. Google DeepMind demonstrates how scaled foundation models can serve as direct simulation backbones for digital spaces.
A distinguishing capability of Genie 4 is its capacity for live runtime modifications guided by continuous textual prompts. Users can alter an ongoing simulation on the fly by introducing sudden weather shifts, adding new interactive characters, or changing the genre of the scene entirely. The underlying model smoothly incorporates these modifications without resetting the session or compromising spatial coherence. This dynamic responsiveness provides creators with unprecedented flexibility for spontaneous scenario testing and narrative shifts.
Beyond visual generation, Genie 4 features natively integrated audio synthesis that operates in complete lockstep with the visual environment. The model generates spatial ambient soundscapes that adjust to the physical layout and atmospheric parameters of the generated environment. Furthermore, it composes dynamic background music and synthesizes interactive spoken dialogues for non-player characters in real time. Because audio and visuals emerge from a single unified architecture, spatial sound and on-screen events remain coherent.
Early adopters and creative professionals are already exploring practical workflows for Genie 4 across media production and video game development. In cinematic production, filmmakers use the environment for virtual set exploration, evaluating camera angles and spatial layouts before principal photography begins. For game developers, the platform facilitates experimental instant prototyping of playable mechanics without requiring traditional game engines. Conceptual environments and interactive mechanics can thus be tested within minutes directly through prompting.
Google DeepMind is currently offering Genie 4 as an exclusive Research Preview to an initial group of vetted testers and developers. Access to the environment is facilitated through Project Genie as well as specialized endpoints within the Gemini API. This measured rollout enables the research team to gather operational data on how users manipulate physically reactive generative worlds. The initiative signals a broader shift in digital entertainment, where generative neural models begin to complement or replace established asset-heavy development pipelines.