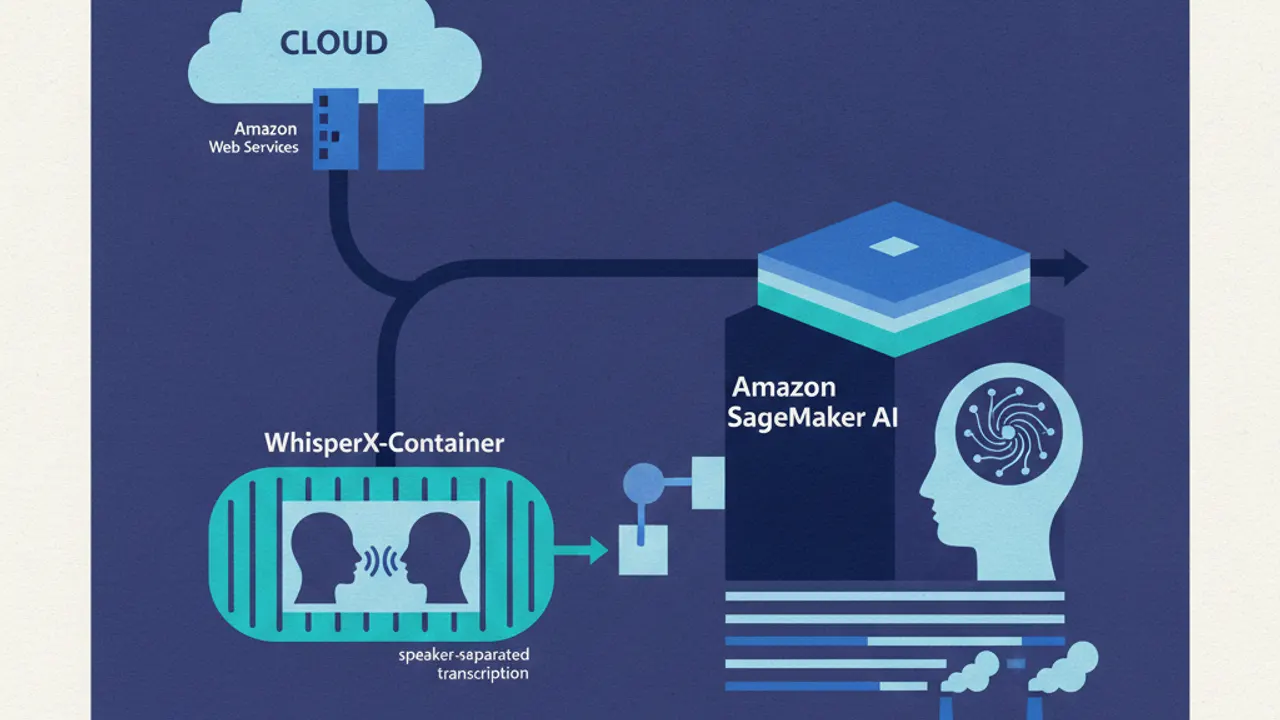
Amazon Web Services has detailed the deployment of its dedicated speech processing container for cloud environments. According to the release, the AWS WhisperX Deep Learning Container "packages Whisper, wav2vec2 forced alignment, and speaker diarization into a GPU-ready image" to streamline setup. This unified container setup enables users to generate "word-level, speaker-labeled transcription" directly within the platform.
The environment is built to support different operational requirements through Amazon SageMaker AI. Organizations can deploy the image to "Amazon SageMaker AI real-time and asynchronous endpoints" depending on their workload latency needs. The deployment guidance also addresses key operational requirements, detailing "the GPU AMI pin, scaling, and cost controls" for managing infrastructure expenses.