Skip to content
AI ConnectPowered by VELENTIS
AI-generated1 min

AWS Outlines Amazon Bedrock Prompt Caching Scenarios to Lower Costs

Prompt caching in Amazon Bedrock can reduce input token expenses by up to 90 percent across several Converse API scenarios, according to AWS.

This article was AI-generated and published automatically. Context, labelling and all sources at the end of the article.

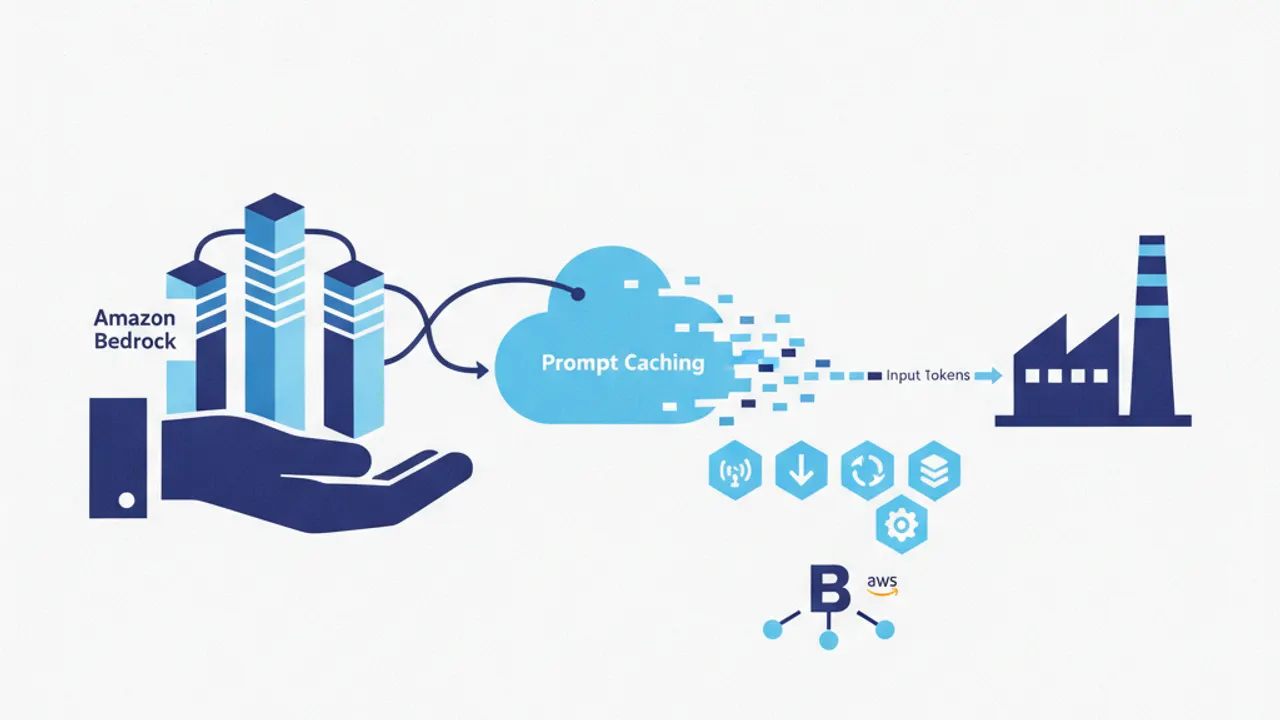
(KI-generiertes Symbolbild: Gemini / AI Connect)

Amazon Web Services has detailed how prompt caching in Amazon Bedrock can significantly lower computational expenses when developers query foundation models. According to the cloud provider, caching mechanisms "can cut input token costs by up to 90% when you repeatedly send the same context to foundation models." By avoiding the need to process duplicate context repeatedly, systems can curb both financial expenditure and request latency.

The approach is demonstrated across multiple developer workflows using Amazon's unified interface. AWS published a guide covering "six practical prompt caching scenarios using the Converse API" to address common architectural patterns. These specific use cases include "message content, system prompt, tool definition, mixed TTL, tenant isolation, and LangChain integration," providing patterns for frameworks and multi-user environments.

What this means for you

Enterprises running generative AI workloads with large, static prompts can achieve substantial operational savings by adopting prompt caching. Applying these architectural scenarios allows engineering teams to keep API costs predictable while maintaining multi-tenant safety and framework compatibility.

Evidence

Solidly sourced
46/100
  • AWS demonstrated prompt caching across six distinct implementation scenarios using the Converse API.

    single source
    Quote

    six practical prompt caching scenarios using the Converse API

  • The outlined Bedrock caching setups span message content, system prompts, tool definitions, TTL management, tenant isolation, and LangChain integration.

    single source
    Quote

    message content, system prompt, tool definition, mixed TTL, tenant isolation, and LangChain integration.

The evidence score is computed, not hand-set: from confidence, the number of sources and the share of verified statements.

Source & transparency

As of: September 15, 2026

AI-generatedAI-generated: produced automatically from vetted sources with technical quality checks (source, quote and figure verification); no human sign-off of each item before publication

Sources
1
Verified statements
0 / 2
Evidence score
46Solidly sourced

Want to put this into practice?

We connect you with suitable AI providers from the DACH region, free of charge and without obligation.

What's next?